Explanation, Advantages & Use Cases
What is Edge Computing?
Edge computing refers to the pre-processing of data close to the source. This allows calculations to be carried out in real time and relieves the burden on local networks. In this article, we will explain why edge computing is playing an increasingly important role in industrial environments and other areas and which technologies are being used to implement it.
Definition
What does edge computing mean?
Edge computing is the processing of data directly at or near its source – such as at the machine or in the plant network – instead of first sending it to a remote data centre or to the cloud.
Edge computing refers to the processing of data directly at or near the source. The term “edge” refers to decentralized data processing at the “edge of the network”. In manufacturing, this edge is where data is generated: at machines, controllers and sensors in the Industrial Internet of Things (IIoT).
Edge computing can reduce the amount of data that needs to be transmitted to a more distant data centre for processing. This not only conserves network bandwidth, but also avoids delays in data processing – in other words, it keeps latency low. This makes edge computing technology particularly relevant when real-time results are required.
The areas of application for edge computing are diverse: from condition monitoring of individual machines and industrial production management to connecting several plants. Edge computing also provides an important foundation for applications where delays are unacceptable, such as monitoring limit values or quality inspection using image recognition directly on the line.
In many industrial environments, edge computing and cloud computing are combined strategically, with large volumes of data being collected from a wide variety of sources, pre-processed locally and then transmitted to a central cloud environment.
What are the advantages of edge computing?
In contrast to processing all data in a central data centre, local pre-processing of data using edge computing technology offers a number of advantages:
Faster and more efficient data processing
When data does not have to be transmitted over long distances, it can be analyzed and processed faster. This improves the performance of applications that require low latency, such as monitoring limit values or image processing in quality inspection. Similarly, the real-time availability of plant data plays a role in industrial environments in order to automate processes and respond to malfunctions as quickly as possible.
Lower network utilization
When less data is sent over the network, bandwidth is conserved and network costs are reduced. This is particularly relevant when large amounts of data are generated by sensors and other devices.
Processing large amounts of data
As part of local pre-processing, data can be filtered, aggregated or compressed before it is sent to central servers or cloud platforms. This makes it possible to transfer only the relevant data and not put unnecessary strain on storage and computing capacity.
Improved security and data privacy
When data does not need to be transmitted over the internet, it is less vulnerable to attacks or data breaches. In special cases, edge computing allows data to be isolated and processed in accordance with local laws and regulations, making it easier to meet compliance requirements.
Comparison
Edge, fog and cloud computing compared
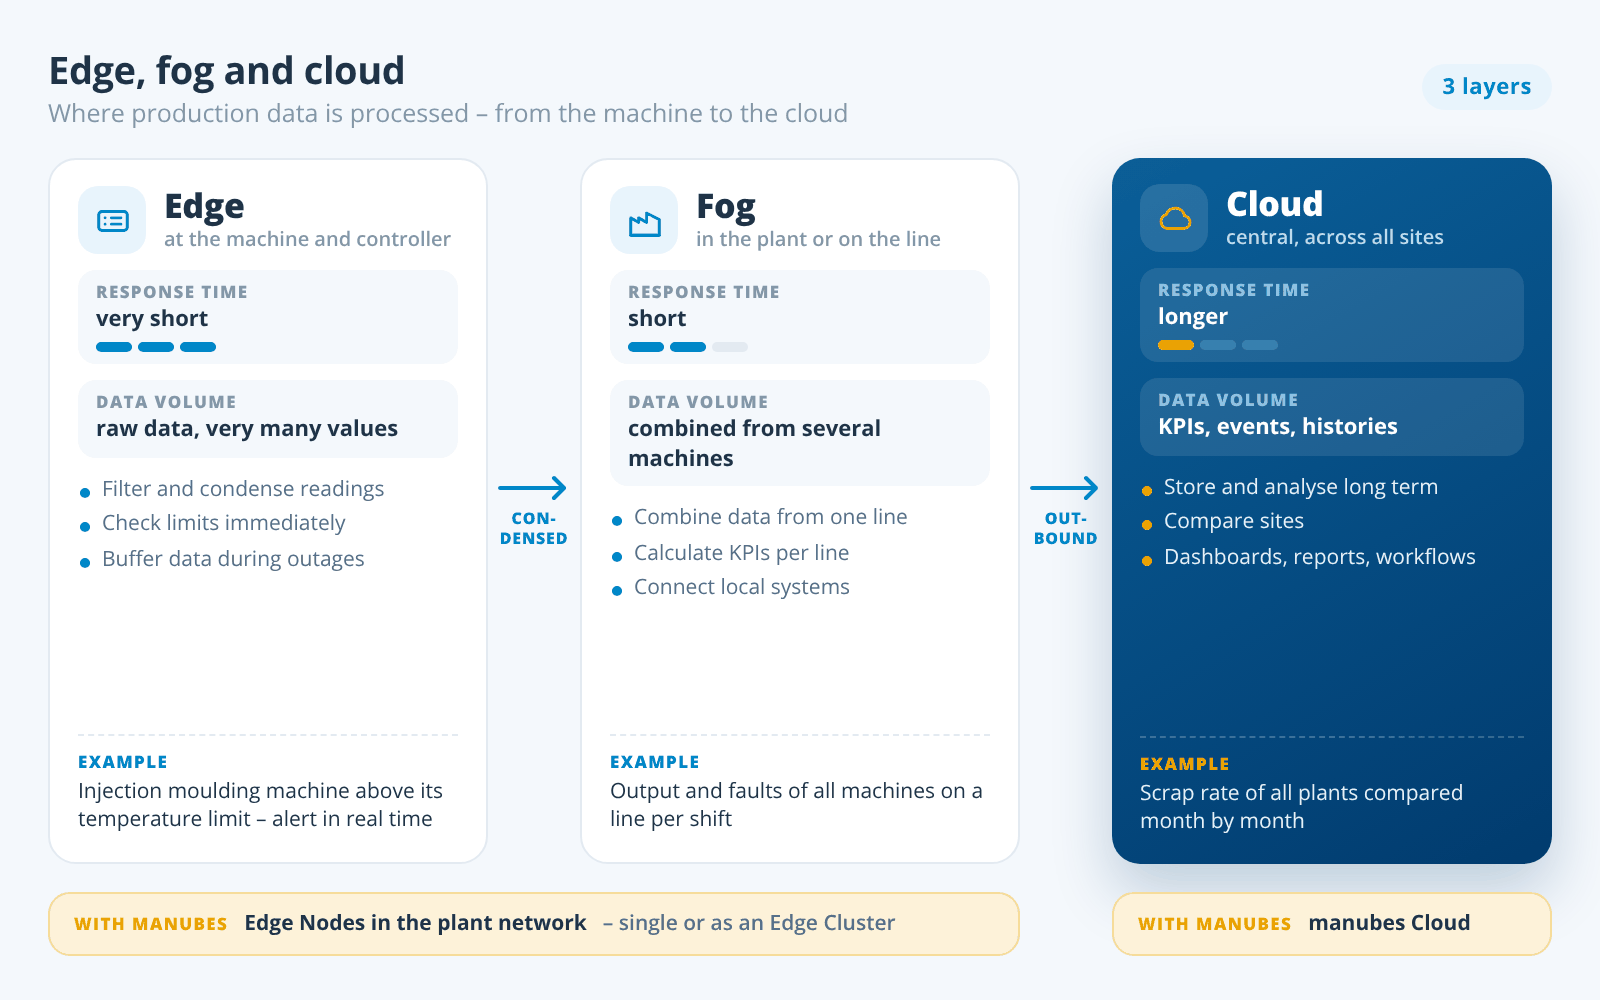
Edge, fog and cloud are three layers of the same distributed architecture. The main difference is how close to the data source the computing takes place. Fog computing describes the intermediate layer: computers in the local network that combine data from several edge devices before it is sent to the cloud.
| Criterion | Edge computing | Fog computing | Cloud computing |
|---|---|---|---|
| Where data is processed | Directly at the machine, controller or sensor | In the local network, e.g. a server or gateway in the plant or on the line | Centrally in data centres, independent of location |
| Latency | Very low | Low | Higher, depending on the connection |
| Data volume | Raw data with many individual values | Combined data from several machines | Condensed KPIs, events and histories |
| Scalability | Limited by the hardware on site | Limited by the infrastructure in the plant | High, resources on demand |
| Typical task | Filtering, checking limits, buffering | Combining data from one line, connecting local systems | Storing, analyzing, visualizing, comparing sites |
| Example in manufacturing | Injection moulding machine above its temperature limit – alert in real time | Output and faults of all machines on a line per shift | Scrap rate of all plants compared month by month |
The boundaries between edge and fog are fluid; many vendors combine both layers under the term “edge”.
How do edge and cloud computing complement each other?
In cloud computing, (external) computer resources are used to centrally store and process large amounts of data. The most important advantages of cloud computing include the scalability of cloud environments and location-independent access to cloud resources.
In practice, edge computing and cloud computing complement each other very well: the decentralized data processing of edge computing reduces the amount of data that needs to be transported to the cloud. At the same time, cloud platforms serve as a central infrastructure for processed edge data and enable further storage, analysis and visualization – with all the advantages of cloud computing included.
Companies that combine edge computing and cloud computing benefit from a hybrid architecture that combines the advantages of local data processing with the scalability and performance of cloud environments.
Use Cases
Where is edge computing used?
Edge computing is primarily used in cases where large volumes of data need to be processed quickly, securely and in a resource-efficient manner.
In many areas, it is impossible or impractical to send all data to remote data centres first. In manufacturing, this applies to controllers, cameras for quality inspection and sensors that deliver many readings per second, for example.
The most important areas of application for edge computing include the following:
- Industrial manufacturing
- Logistics and transport
- Health monitoring
- Security technology
- Home automation (Smart Home)
- Autonomous driving
In industrial production, edge computing enables the real-time evaluation of large amounts of data from sensors, control systems and other sources. This data can be used to monitor the status of systems and implement predictive maintenance.
Typical use cases in manufacturing
These scenarios show where edge computing makes a difference on the shop floor:
Condition monitoring
Predictive maintenance
Quality inspection using image recognition
Energy monitoring
Intralogistics
Multiple sites
Optimize your production with manubes
manubes offers a central platform for production data management, data visualization and workflow-based process automation.
Manufacturers gain access to a variety of innovative tools in order to quickly develop their own applications – tailored to their requirements.
Industry
Edge computing in manufacturing
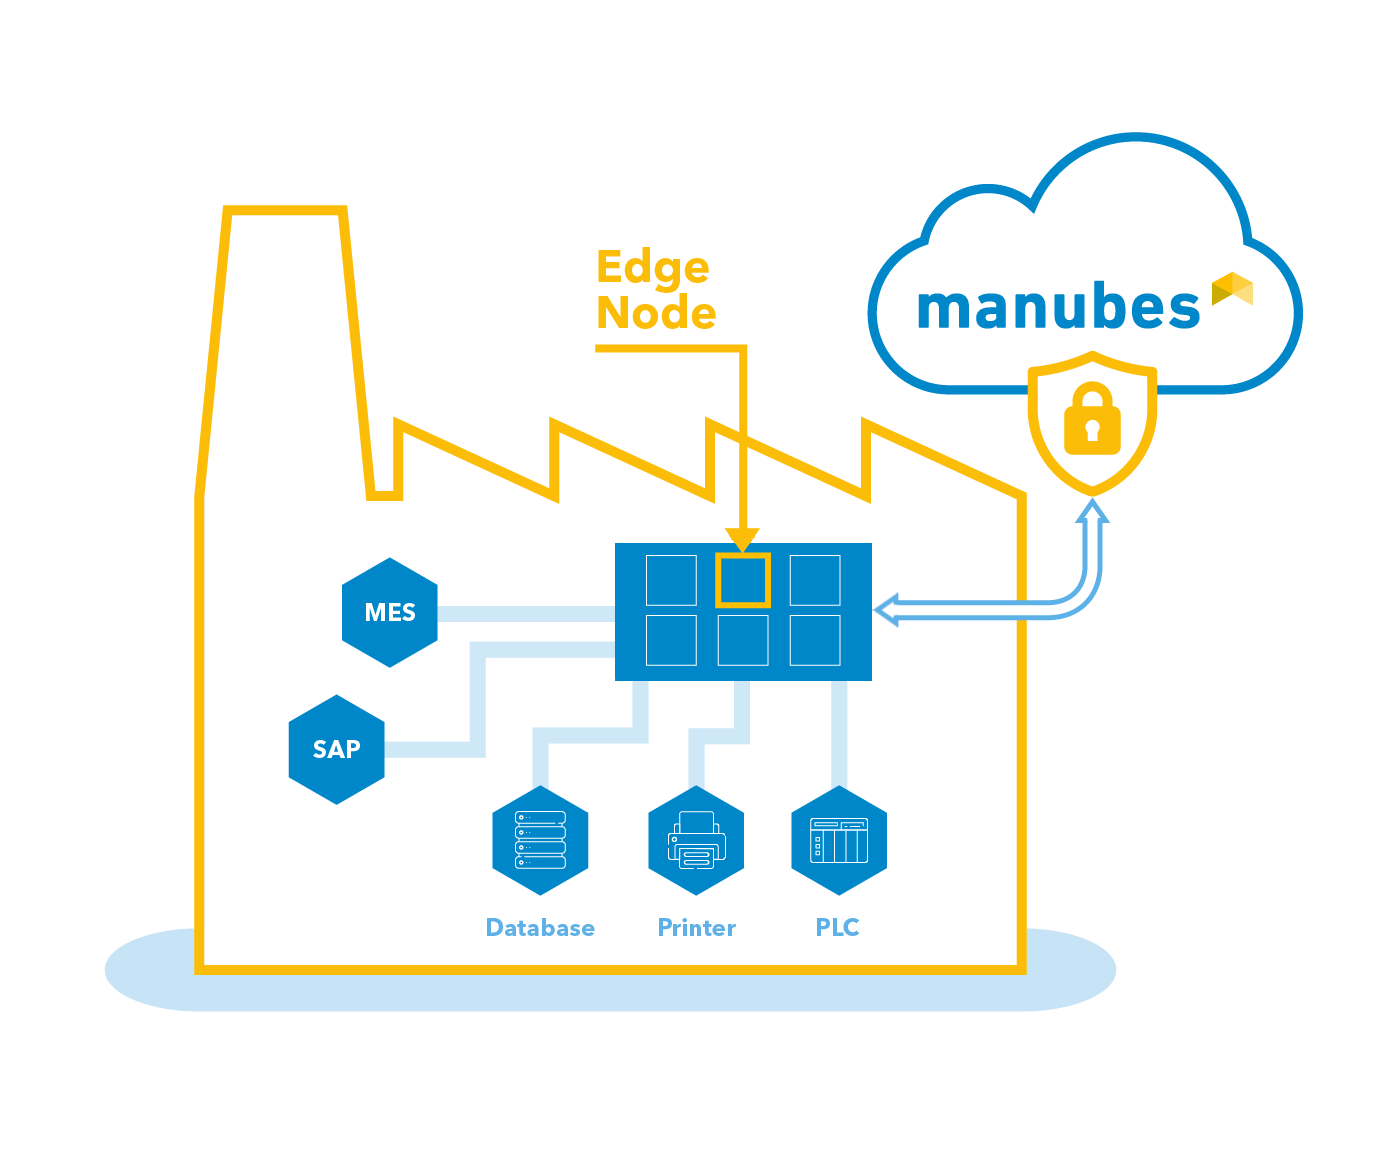
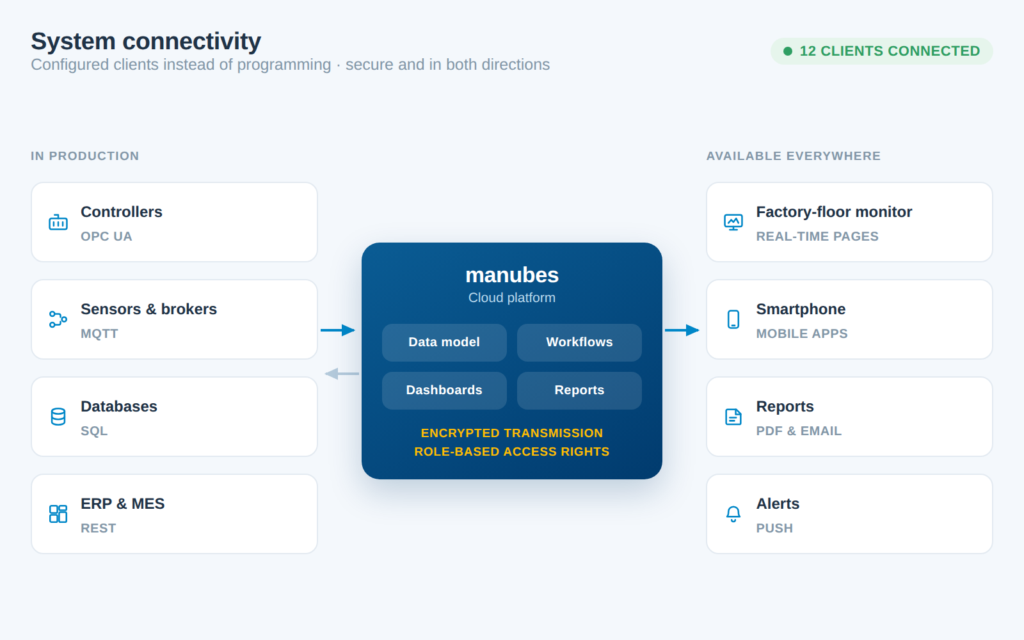
In manufacturing, edge computing connects the machines on the shop floor with central platforms in the cloud. Edge devices in the plant network read data from controllers, sensors and local systems, pre-process it and only transmit what is needed.
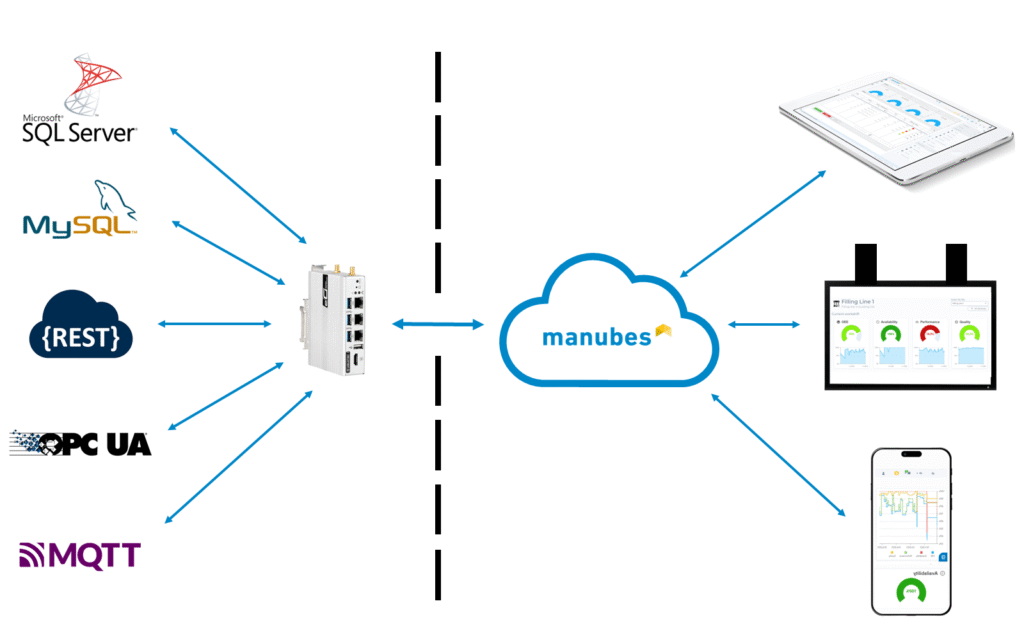
The cloud platform manubes uses this concept: Edge Nodes run in the local network and provide secure, bidirectional connectivity between machines, databases, systems such as MES and ERP and the manubes Cloud. Data from PLCs and sensors is collected via OPC UA or MQTT.
- Pre-processing: the Edge Node filters and condenses data and checks limit values on site.
- Buffering: if the connection is lost, the Edge Node buffers the data and transmits it afterwards.
- High availability: several Edge Nodes form an Edge Cluster that compensates for the failure of a single device.
- Outbound connection: data is sent to the cloud exclusively outbound and encrypted – without any inbound connections to the production network.
The graphic shows how the manubes edge components work together.
Technical Implementation
How can edge computing be implemented?
Edge computing can be implemented in various ways. In many cases, controllers, cameras, routers or other devices are already equipped with the capacity for local data processing.
Especially for industrial applications, special hardware and software components are also available, allowing manufacturers to leverage the benefits of edge computing within existing structures.
Edge devices
Edge devices are hardware components that enable data processing close to the source. This requires them to have powerful processors and memory, on top of being able to collect data and transmit processed data to other systems. The latter is achieved with the help of various protocols and interface standards (see next section).
In order to deploy, run and manage applications on (Linux-based) edge devices, a container virtualization software such as Docker can be used. Various manufacturers offer specialized edge devices and edge servers for industrial use cases – which of them are suitable for manubes is shown in our comparison of industrial edge devices.
Which edge devices work with manubes?
Industrial edge devices compared – by Docker capability, OPC UA and manubes compatibility.
Compare edge devicesProtocols and interfaces
Suitable protocols and interfaces are needed to transport data between data sources, edge devices, data centres and cloud platforms.
Wireless transmission and mobile communications standards such as Bluetooth or 5G play an important role for many edge computing use cases.
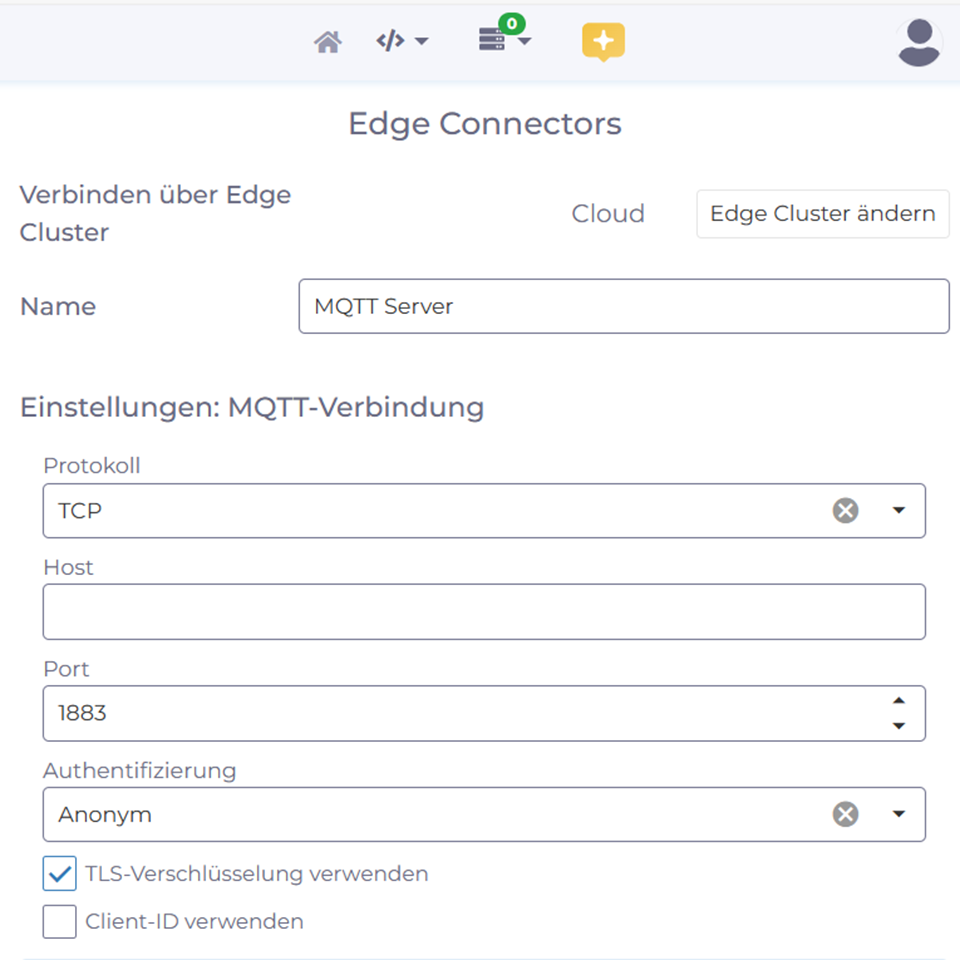
At the application layer, MQTT is one of the most important network protocols for data transmission between IoT devices and other applications due to its resource-saving implementation. Within industrial environments, the OPC UA standard is also used frequently.
Challenges and drawbacks of edge computing
Edge computing does not solve every problem. Companies should be aware of four challenges – and know how to address them:
Costs of distributed hardware
Edge computing requires computing power on site; every plant, and often every line, needs its own devices. Countermeasure: only handle time-critical tasks at the edge and use existing Docker-capable industrial PCs or edge devices.
Maintaining and updating many devices
Many distributed devices mean many software versions. Countermeasure: deploy applications as containers and manage them centrally instead of maintaining each device individually.
Device or connection failures
If an edge device or the connection to the cloud fails, gaps in the data can occur. Countermeasure: buffer data and design devices redundantly. In manubes, the Edge Node buffers data when the connection is lost, and an Edge Cluster protects against the failure of a single device.
Security of distributed devices
Every edge device is a potential point of attack and often physically accessible. Countermeasure: operate devices in the protected production network, only establish outbound and encrypted connections and restrict access to what is necessary.
Edge computing with manubes
Connect machines securely via Edge Nodes, pre-process data on site and visualize it in the manubes Cloud – without inbound connections to the production network.
Try manubes for freeFuture Outlook
What role will edge computing play in the future?
Edge computing is already being widely used in various areas, including the Internet of Things (IoT), industrial automation and healthcare.
With the ongoing development of technologies such as 5G and the emergence of increasingly powerful edge devices, the ability to process data locally is constantly improving. A further increase in the importance of edge computing is therefore predicted for the future. Due to advances in artificial intelligence, the number of use cases in which real-time data is required could grow even faster.
Edge AI refers to AI models that run directly on the edge device instead of in the cloud – for example for image recognition in quality inspection or for detecting unusual machine states. The results are then sent to the cloud, where they are stored, visualized and linked with other data. Find out more in our article on AI in production.
More and more manufacturers are also relying on the benefits of edge computing in industrial production. Companies with multiple sites in particular are using the technology to quickly gain insights from huge amounts of sensor and plant data without overloading their existing infrastructure.
Frequently asked questions about edge computing
What is edge computing in simple terms?
Edge computing means that data is processed where it is generated instead of first being sent to a remote data centre. In manufacturing, this could be a small computer next to the machine that checks readings immediately and only passes the important results on to the cloud. This keeps latency low and saves bandwidth.
What is the difference between edge and cloud computing?
Edge computing processes data in a decentralized way at the source, cloud computing centrally in data centres. The edge is faster and relieves the network, while the cloud scales better and can be accessed from anywhere. In manufacturing, both are usually combined: edge devices pre-process machine data, the cloud stores, analyzes and visualizes it.
What is the difference between edge computing and fog computing?
Fog computing is the layer between edge and cloud. Edge devices work directly at the machine or sensor, while fog nodes in the local network combine the data from several edge devices, such as a whole production line, before it is sent to the cloud. The boundaries are fluid; many vendors combine both layers under the term “edge”.
What is edge computing in AI?
Edge AI means artificial intelligence that runs directly on the edge device instead of in the cloud. A trained model detects defects in camera images directly on the line, for example. Because the images do not have to be transmitted, results are available faster and the data volume drops. Training and analysis across many sites usually still take place in the cloud.
What is an edge device?
An edge device is a computer close to the data source that collects data, pre-processes it and passes it on to other systems. In industry, these are robust industrial PCs, edge gateways or edge controllers, often running Docker for applications. Which edge devices are suitable for manubes is shown in our comparison of industrial edge devices; how to connect one is explained in our step-by-step guide.
What are examples of edge computing in manufacturing?
Typical examples are condition monitoring of machines, predictive maintenance, quality inspection using image recognition, energy monitoring and connecting several plants. In manubes, Edge Nodes in the plant network take on this task: they read data via OPC UA or MQTT, pre-process it, buffer it when the connection is lost and transmit it to the cloud in encrypted form.
What are the drawbacks of edge computing?
The main drawbacks are the costs of distributed hardware, the effort of maintaining and updating many devices, possible failures of individual devices and additional points of attack. Countermeasures include containers and central management, buffering and redundant devices such as an Edge Cluster, and connections that are only established outbound and encrypted.
Product video: Get to know manubes
Further information
Try manubes for free
Test the different manubes features in your personal cloud environment.
Get started
